Fine-tuning on one example, and knowing when to stop
audio
speech
fine-tuning
week-5
Week 5 was fine-tuning Whisper on a single clip, because one example makes visible what a held-out score hides. It also makes visible what you pay for it.
Author
Rosh Beed
Published
September 18, 2026
Week 5: speech. The project was fine-tuning Whisper [1] on exactly one clip — a recording where the base model mishears my name — and watching a handful of gradient steps correct it.
One example rather than a dataset, on purpose. Fine-tuning is normally reported as a number moving on a held-out set, which is honest and tells you nothing about what actually happened. With one example you can watch the mechanism.
Two things become visible that way. The first is that it works, quickly. The second is what it costs, which is the part I hadn’t appreciated.
First, how audio becomes something a transformer can read
A transformer needs a sequence of vectors. A waveform is a very long list of amplitudes — 16,000 numbers a second — with the useful structure spread across frequencies rather than sitting in the samples.
The standard answer is a log-mel spectrogram, and it’s three steps:
Chop the waveform into short overlapping frames and take the Fourier transform of each. Now you have how much energy sits at each frequency, over time.
Squash the frequency axis onto the mel scale, which spaces bands the way hearing does — fine detail low down, coarser high up. 201 frequency bins become 80 mel bands.
Take the log, because loudness is perceived multiplicatively.
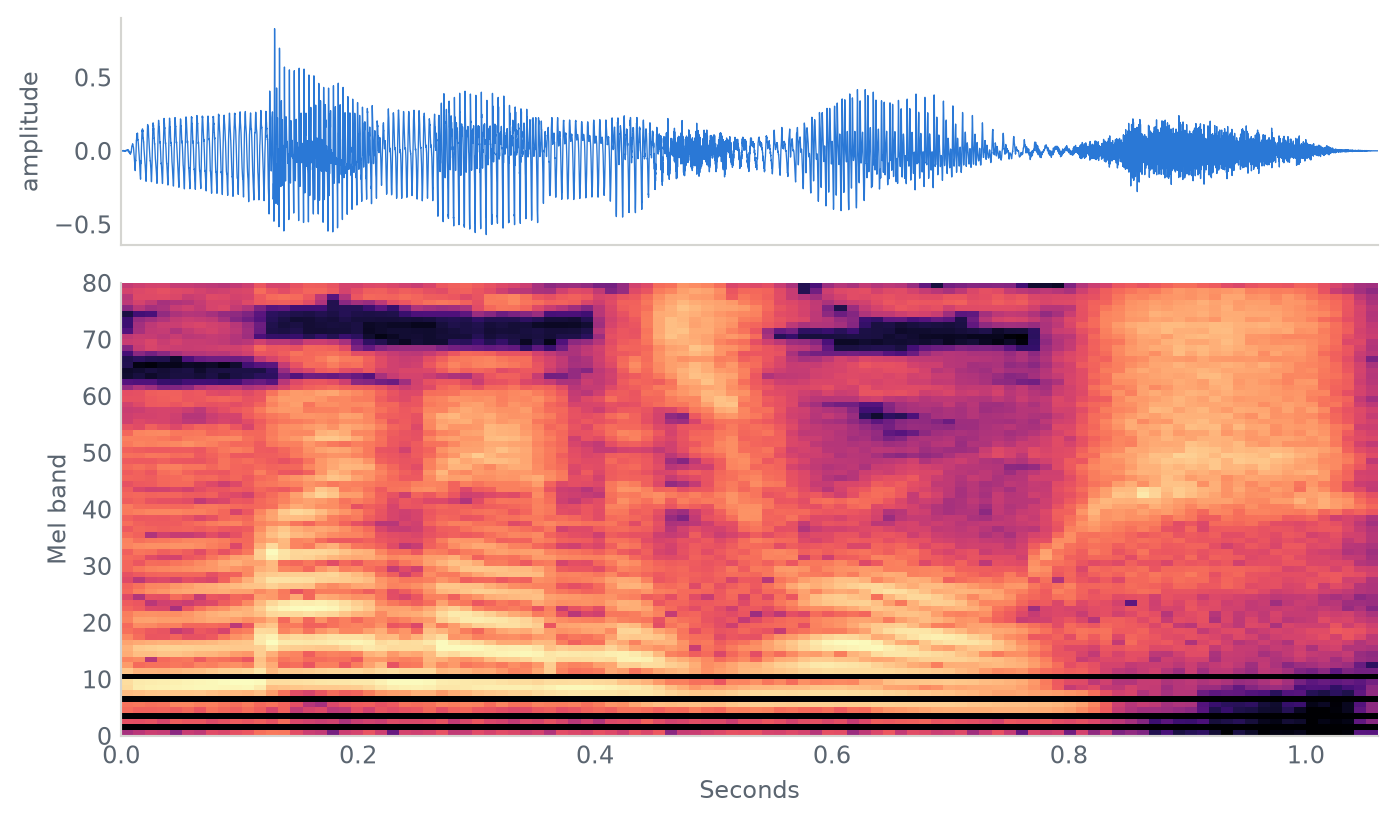
What comes out is a picture: 80 rows by however many frames. That’s what the model sees. Here it is on the actual clip from the project, computed from scratch.
Figure 1: One second of speech, before and after. The model never sees the waveform on top; it reads the picture underneath.
A speech model small enough to watch
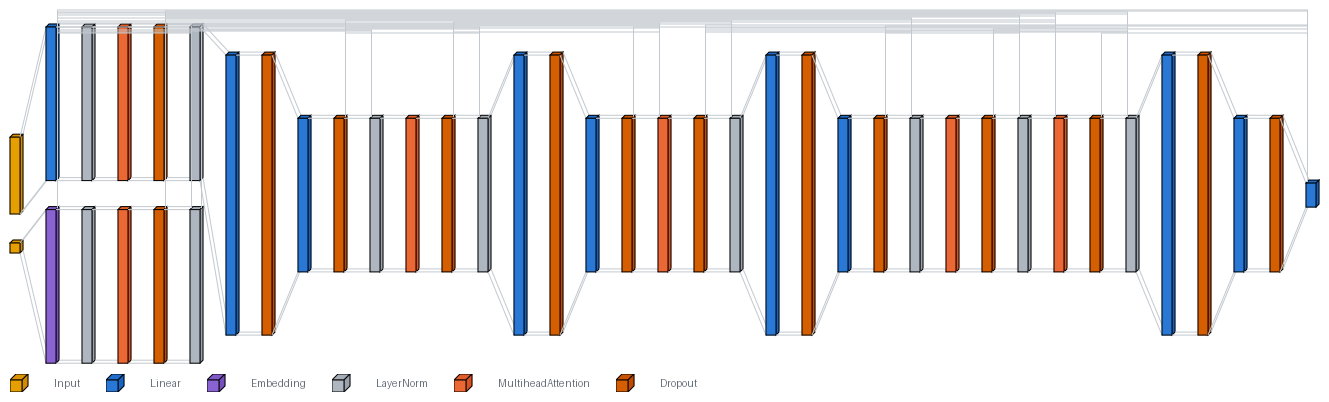
Whisper is an encoder–decoder transformer over exactly that picture — the same shape as the multi-digit reader from week 3, with a spectrogram in place of an image.
I can’t run Whisper while this page builds, so here’s the same architecture at a size that trains in seconds, on a language I can synthesise: words of three letters, where each letter is a tone at its own frequency. Speaking a word means playing its tones in order; transcribing it means reading them back.
Show the code
import torchimport torch.nn as nnRATE, TONE_SECONDS, NOISE =8000, 0.08, 0.15ALPHABET ="abcdefgh"TONES = {c: 300*1.28** i for i, c inenumerate(ALPHABET)}rng = np.random.default_rng(0)WORDS =sorted({"".join(rng.choice(list(ALPHABET), 3)) for _ inrange(60)})[:40]def speak(word, seed, shift=1.0):"""Play each letter's tone in turn, with a little jitter and noise.""" g = np.random.default_rng(seed) parts = []for c in word: t = np.arange(int(RATE * TONE_SECONDS)) / RATE f = TONES[c] * shift * (1+0.02* g.normal()) parts.append((np.sin(2* np.pi * f * t) +0.4* np.sin(4* np.pi * f * t))* np.hanning(len(t))) x = np.concatenate(parts)return (x + NOISE * g.normal(size=len(x))).astype(np.float32)SMALL_FFT, SMALL_HOP, SMALL_MELS =256, 64, 32BANK = mel_filterbank(RATE, SMALL_FFT, SMALL_MELS)def to_picture(x): power = np.abs(stft(x, SMALL_FFT, SMALL_HOP)) **2return np.log10(np.maximum(BANK @ power, 1e-10)).T.astype(np.float32)def build(repeats, seed0): pictures, labels = [], []for index, word inenumerate(WORDS):for k inrange(repeats): pictures.append(to_picture(speak(word, seed0 + index *1000+ k))) labels.append(index)return torch.from_numpy(np.stack(pictures)), torch.tensor(labels)X, Y = build(12, 0)X_test, Y_test = build(4, 500_000)print(f"{len(WORDS)} words, {len(X)} training clips of shape {tuple(X.shape[1:])}")
40 words, 480 training clips of shape (27, 32)
Show the code
LETTERS =sorted(set("".join(WORDS)))START, END =len(LETTERS), len(LETTERS) +1VOCAB =len(LETTERS) +2DIM, FRAMES =64, X.shape[1]TARGET = torch.tensor([[START] + [LETTERS.index(c) for c in w] + [END] for w in WORDS])class Transcriber(nn.Module):"""An encoder over the spectrogram, a decoder that spells the word."""def__init__(self):super().__init__()self.input= nn.Linear(SMALL_MELS, DIM)self.audio_positions = nn.Parameter(torch.randn(1, FRAMES, DIM) *0.02)self.encoder = nn.TransformerEncoder( nn.TransformerEncoderLayer(DIM, 4, 4* DIM, batch_first=True, norm_first=True, dropout=0.0), 2)self.embed = nn.Embedding(VOCAB, DIM)self.text_positions = nn.Parameter(torch.randn(1, 5, DIM) *0.02)self.decoder = nn.TransformerDecoder( nn.TransformerDecoderLayer(DIM, 4, 4* DIM, batch_first=True, norm_first=True, dropout=0.0), 2)self.out = nn.Linear(DIM, VOCAB)def forward(self, picture, tokens): memory =self.encoder(self.input(picture) +self.audio_positions) h =self.embed(tokens) +self.text_positions[:, :tokens.shape[1]] mask = nn.Transformer.generate_square_subsequent_mask(tokens.shape[1])returnself.out(self.decoder(h, memory, tgt_mask=mask))torch.manual_seed(0)model = Transcriber()optimiser = torch.optim.AdamW(model.parameters(), lr=1e-3, weight_decay=0.01)generator = torch.Generator().manual_seed(0)@torch.no_grad()def transcribe(pictures): tokens = torch.full((len(pictures), 1), START)for _ inrange(3): tokens = torch.cat([tokens, model(pictures, tokens)[:, -1].argmax(-1, keepdim=True)], 1)return tokens[:, 1:]def spell(ids):return"".join(LETTERS[i] for i in ids if i <len(LETTERS))def accuracy():return (transcribe(X_test) == TARGET[Y_test][:, 1:4]).all(1).float().mean().item()
Figure 2: Whisper’s shape at 1/1000th the size: a spectrogram into the encoder, the text so far into the decoder, one letter out.
Show the code
for epoch inrange(20): perm = torch.randperm(len(X), generator=generator)for i inrange(0, len(perm) -64, 64): b = perm[i:i +64] target = TARGET[Y[b]] loss = nn.functional.cross_entropy(model(X[b], target[:, :-1]).reshape(-1, VOCAB), target[:, 1:].reshape(-1)) optimiser.zero_grad() loss.backward() optimiser.step()print(f"transcribes {accuracy():.1%} of held-out clips exactly right")
transcribes 99.4% of held-out clips exactly right
Now an accent it has never heard
The base model has only ever heard these tones at their standard frequencies. Say a word with everything shifted up 10% — a different voice, the same word — and it mishears.
Show the code
WORD, SHIFT ="acd", 1.10one_clip = torch.from_numpy(to_picture(speak(WORD, 999, SHIFT))).unsqueeze(0)one_target = TARGET[WORDS.index(WORD)].unsqueeze(0)print(f"the word is {WORD!r}")print(f"the model hears {spell(transcribe(one_clip)[0].tolist())!r}")print(f"and it is otherwise fine: {accuracy():.1%} on the clean test clips")
the word is 'acd'
the model hears 'adc'
and it is otherwise fine: 99.4% on the clean test clips
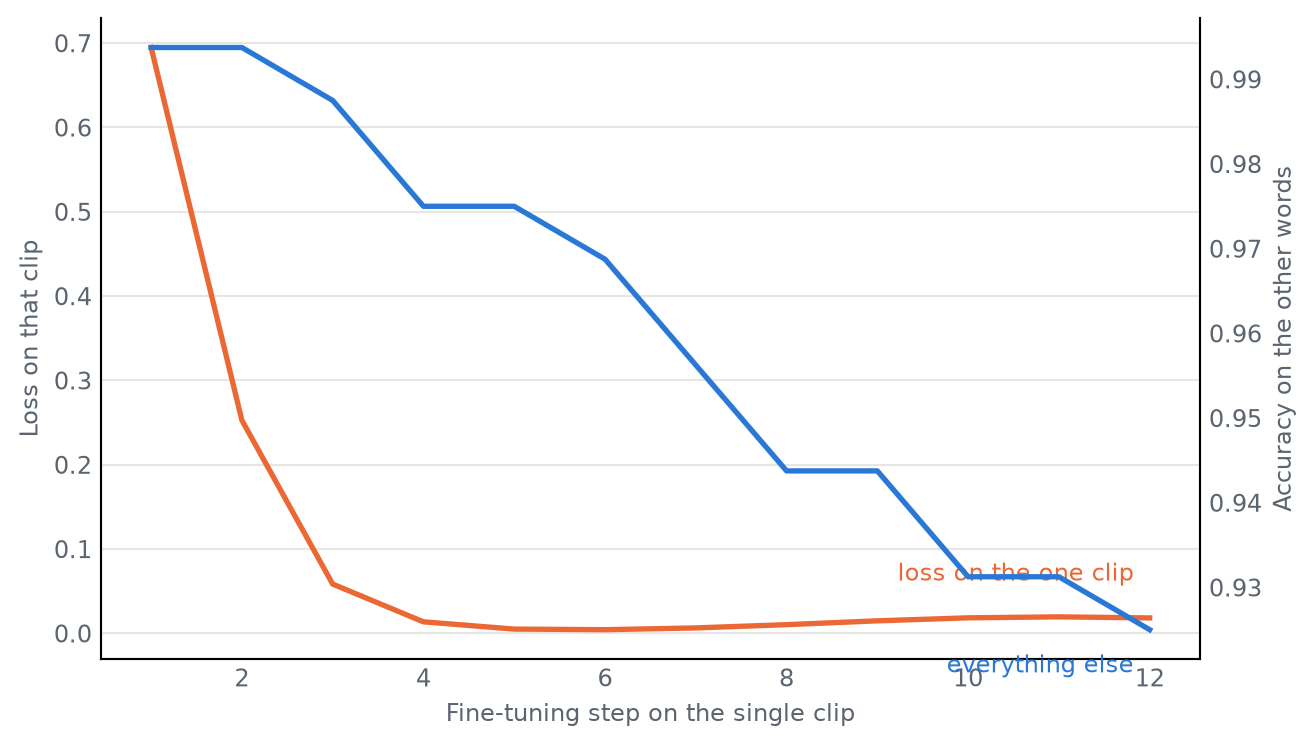
This is the situation the project was in: a model that works, and one specific thing it gets wrong. So fine-tune it on that one clip and nothing else, and watch both numbers at once.
from _style import figurefig, ax = figure(height=4.0)ax.plot(steps, losses, color=COLOURS[1], linewidth=2)style_axes(ax, "Fine-tuning step on the single clip", "Loss on that clip")ax.annotate("loss on the one clip", xy=(steps[-1], losses[-1]), xytext=(-6, 14), textcoords="offset points", ha="right", fontsize=9, color=COLOURS[1])right = ax.twinx()right.plot(steps, clean, color=COLOURS[0], linewidth=2)right.set_ylabel("Accuracy on the other words", color=MUTED, fontsize=9)right.tick_params(colors=MUTED, labelsize=9, length=0)right.spines["top"].set_visible(False)right.annotate("everything else", xy=(steps[-1], clean[-1]), xytext=(-6, -16), textcoords="offset points", ha="right", fontsize=9, color=COLOURS[0])fig.tight_layout()
Figure 3: The fix lands almost immediately. Everything after that is the model memorising one clip at the expense of the other forty words.
What that shows
The fix is cheap. Two gradient steps and the model hears the word correctly. That’s the appealing part, and it’s real — on the actual project a handful of steps on one clip corrected a name the base model consistently got wrong.
The loss goes to nearly zero, and that is not good news. One example, a loss of 0.004 — the model has memorised a single clip. Memorisation is precisely what you’re asking for here, and it’s also the thing that goes wrong when you scale this up without noticing.
You pay for it somewhere you weren’t looking. Accuracy on the other 39 words drops steadily from step 4 onward, and by step 12 it has given up several points to keep improving on a clip it already got right. Nothing in the fine-tuning loop reports that. You have to go and measure it.
So the interesting question isn’t whether fine-tuning works. It’s when to stop, and the only way to answer it is to keep evaluating the thing you’re not training on.
One Whisper-specific trap
Worth writing down because it cost me time and produced no error at all.
Whisper’s tokenizer starts a transcript with a <|startoftranscript|> token. It is tempting to pass the tokenizer’s output straight through as the training labels. Don’t: the model prepends decoder_start_token_id itself when it shifts the labels right, and that token is start-of-transcript. Pass the tokenizer’s output unchanged and every position is off by one.
Nothing raises. The loss goes down. The model is simply learning a different task than the one you meant.