Contrastive Pre-training and a Fine-tuned Adapter: Captioning with CLIP and Qwen
multimodal
vision
language
A frozen CLIP encoder, a frozen Qwen decoder, and the 1.5M-parameter adapter between them that is the only thing trained.
Author
Rosh Beed
Published
June 29, 2026
Multimodal transfer learning: merge existing models, so that between them they do something neither was trained for.
A vision transformer can be built from scratch and trained end to end. That works when the task is small and cheap to supervise. This one is neither.
There’s no dataset here big enough to teach vision and language from scratch, and no need for one. Models that understand images already exist. So do models that write English.
The task is to connect them.
Cross-Attention or a Prefix Token
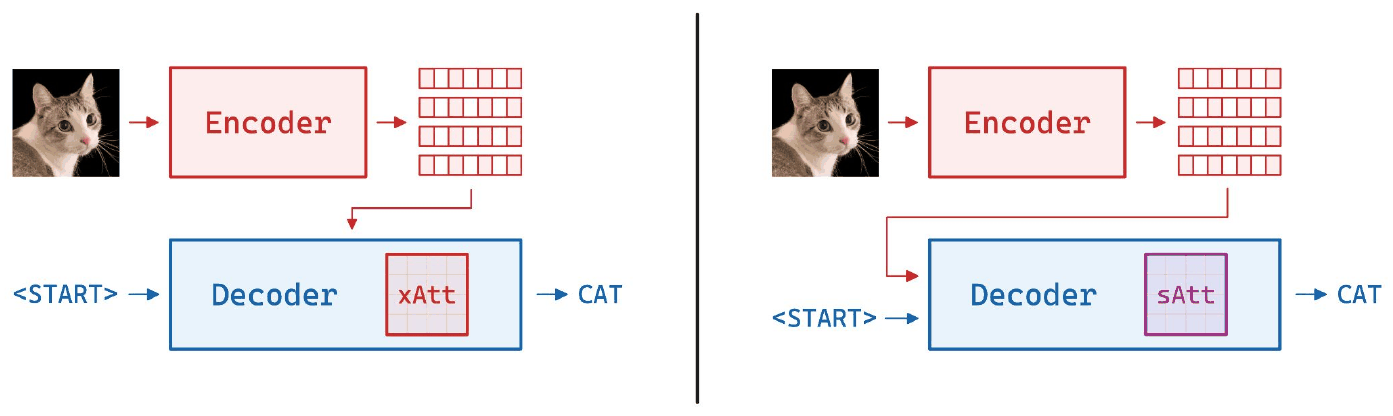
This is the decision it turns on, and both options are already familiar.
xAtt, cross-attention. A dedicated attention layer inside the decoder that looks at the encoder’s output at every generation step. This is exactly what the multi-digit reader did last week.
sAtt, self-attention. Project the image into the language model’s embedding space and put it in the sequence as if it were a token. Ordinary self-attention then does the rest, and the language model is not modified at all.
The second is cheaper in every way that matters here.
No new attention weights to initialise
No architectural change to a model you did not train
The only new parameters sit between the two models’ widths
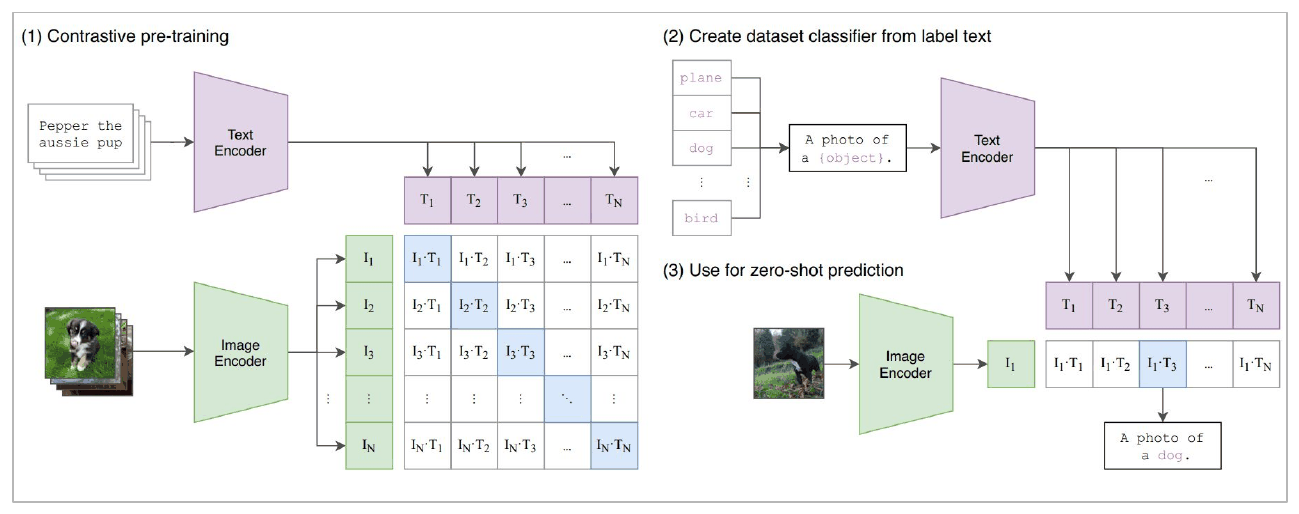
CLIP is trained by pushing an image and its caption to the same place in a shared space, over 400 million pairs. That means its image vectors are already organised by what the picture is about, in a space that was built alongside text.
So the adapter is not being asked to teach a language model to see. It is being asked to translate between two coordinate systems that were each built separately and happen to describe overlapping things.
Building One
The service uses CLIP and Qwen3-0.6B with a 1.58M-parameter adapter between them, and that is what the rest of this post runs.
Neither model was trained with the other in mind. CLIP learned to match images to captions; Qwen learned to continue text. Both stay frozen throughout, and the only thing that trains is the adapter between them.
First, the two of them, and the photographs.
Show the code
import matplotlib.pyplot as pltimport numpy as npimport torchimport torch.nn as nnfrom datasets import load_datasetfrom transformers import AutoModelForCausalLM, AutoTokenizer, CLIPModel, CLIPProcessorDEVICE = torch.device("mps"if torch.backends.mps.is_available() else"cpu")# Chart styling, inlined so this notebook runs on its own.MUTED, AXIS ="#5b6570", "#d5d5d1"CLIP_NAME, QWEN_NAME ="openai/clip-vit-base-patch32", "Qwen/Qwen3-0.6B-Base"SAMPLES, PROMPT, MAX_CAPTION =2_000, "This is a photo of:", 32BATCH, LR, EPOCHS =16, 1e-4, 12ENCODE_BATCH, WRITE_BATCH =128, 32rows = load_dataset("nlphuji/flickr30k", revision="refs/convert/parquet", split=f"test[:{SAMPLES}]")clip_processor = CLIPProcessor.from_pretrained(CLIP_NAME)clip = CLIPModel.from_pretrained(CLIP_NAME).to(DEVICE).eval()tokeniser = AutoTokenizer.from_pretrained(QWEN_NAME)qwen = AutoModelForCausalLM.from_pretrained(QWEN_NAME, dtype=torch.float32).to(DEVICE).eval()for parameter in (*clip.parameters(), *qwen.parameters()): parameter.requires_grad =FalseWIDTH = qwen.config.hidden_sizeprint(f"{len(rows)} images with reference captions")print(f"CLIP {sum(p.numel() for p in clip.parameters()) /1e6:>6.0f}M frozen")print(f"Qwen {sum(p.numel() for p in qwen.parameters()) /1e6:>6.0f}M frozen, "f"{WIDTH} wide")
Both are released models and both are frozen. Nothing in either will receive a gradient at any point below.
The image goes through CLIP once, and what comes out is all the language model will ever know about it.
Show the code
with torch.no_grad():# In batches. One forward over all the images at once holds every layer's# activations for every image, which runs to tens of gigabytes. encoded = []for start inrange(0, len(rows), ENCODE_BATCH): images = [im.convert("RGB")for im in rows[start:start + ENCODE_BATCH]["image"]] pixels = clip_processor(images=images, return_tensors="pt").pixel_values.to(DEVICE)# get_image_features returns a tensor in some transformers versions and an# output object in others; the projection is what CLIP compares text against. encoded.append(clip.visual_projection( clip.vision_model(pixel_values=pixels).pooler_output)) features = torch.cat(encoded)captions = [row["caption"][0] for row in rows]split =int(0.8*len(rows))train_rows, test_rows =list(range(split)), list(range(split, len(rows)))print(f"each image is {tuple(features.shape[1:])} numbers out of CLIP")print(f"{len(train_rows)} for training, {len(test_rows)} held out")print(f"a reference caption: {captions[0]}")
each image is (512,) numbers out of CLIP
1600 for training, 400 held out
a reference caption: Two young guys with shaggy hair look at their hands while hanging out in the yard.
That space was not built for photographs alone. CLIP has a second tower for text that projects into the same 512 numbers, and contrastive training is what pulled a photograph and its caption to the same place in them.
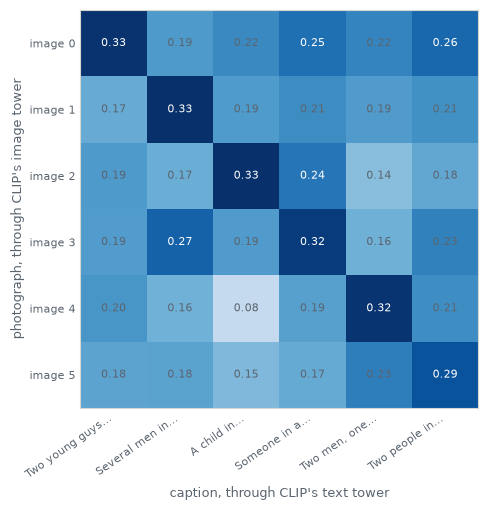
Which is checkable with the vectors already in hand: run the captions through the other tower and compare every image against every caption.
Show the code
SHOWN =6@torch.no_grad()def clip_text(sentences, batch=256):"""Captions through CLIP's other tower, into the same space as the images.""" parts = []for start inrange(0, len(sentences), batch): text = clip_processor(text=sentences[start:start + batch], return_tensors="pt", padding=True, truncation=True, max_length=77).to(DEVICE) parts.append(clip.text_projection(clip.text_model(**text).pooler_output))return torch.cat(parts)image_space = torch.nn.functional.normalize(features, dim=-1)text_space = torch.nn.functional.normalize(clip_text(captions), dim=-1)similarity = image_space @ text_space.Tmatched = torch.arange(len(captions), device=DEVICE)rank1 =float((similarity.argmax(1) == matched).float().mean())paired =float(similarity.diagonal().mean())mismatched =float((similarity.sum() - similarity.diagonal().sum())/ (similarity.numel() -len(similarity)))print(f"its own caption is nearest for {rank1:.1%} of {len(captions)} images, "f"against {1/len(captions):.2%} by chance")print(f"mean similarity matching pair {paired:.4f} | mismatched {mismatched:.4f}")panel = similarity[:SHOWN, :SHOWN].cpu().numpy()fig, ax = plt.subplots(figsize=(6.6, 5.2))ax.imshow(panel, cmap="Blues", vmin=0.0, vmax=panel.max())for i inrange(SHOWN):for j inrange(SHOWN): ax.text(j, i, f"{panel[i, j]:.2f}", ha="center", va="center", fontsize=8, color="white"if panel[i, j] >0.7* panel.max() else MUTED)ax.set_xticks(range(SHOWN), [" ".join(captions[j].split()[:3]) +"\u2026"for j inrange(SHOWN)], rotation=35, ha="right")ax.set_yticks(range(SHOWN), [f"image {i}"for i inrange(SHOWN)])ax.set_xlabel("caption, through CLIP's text tower", color=MUTED, fontsize=9)ax.set_ylabel("photograph, through CLIP's image tower", color=MUTED, fontsize=9)ax.tick_params(colors=MUTED, labelsize=8, length=0)for side in ax.spines.values(): side.set_color(AXIS)fig.tight_layout()
its own caption is nearest for 60.9% of 2000 images, against 0.05% by chance
mean similarity  matching pair 0.3268  |  mismatched 0.1668
Every photograph against every caption, in CLIP’s shared space. The diagonal is the pair that belongs together.
A matching pair scores 0.3268 against 0.1668 for a mismatched one, and across all 2,000 images the right caption is nearest for 60.9% of them, against 0.05% by chance.
That gap is what contrastive training bought, and it is why a small adapter can bridge the two models at all. The image vector already sits near the words that describe it, so the adapter is translating between two coordinate systems rather than teaching a language model to see.
That vector is the whole channel. Every caption below is written from 512 numbers, and anything CLIP discarded when it made them is not recoverable downstream.
The adapter is the only thing that trains: it turns that vector into something shaped like a token Qwen can read.
Show the code
class Adapter(nn.Module):"""CLIP's view of an image, in Qwen's input space, as one prefix token."""def__init__(self, width_in, width_out):super().__init__()self.net = nn.Sequential(nn.Linear(width_in, width_out), nn.GELU(), nn.Linear(width_out, width_out))def forward(self, vectors):returnself.net(vectors).unsqueeze(1)def new_adapter(seed): torch.manual_seed(seed)return Adapter(features.shape[1], WIDTH).to(DEVICE)adapter = new_adapter(0)trainable =sum(p.numel() for p in adapter.parameters())frozen =sum(p.numel() for p in (*clip.parameters(), *qwen.parameters()))print(f"adapter {trainable:>12,} trainable")print(f"frozen {frozen:>12,}")print(f"the adapter is {trainable / (trainable + frozen):.2%} of the whole thing")
adapter     1,574,912 trainable
frozen    747,327,233
the adapter is 0.21% of the whole thing
So a little over a millionth-part of the arrangement moves, and the rest never will.
Before training it, see what the pair does on its own. An untrained adapter hands Qwen one vector of noise, so what comes back can hardly depend on the image.
Show the code
prompt_ids = tokeniser(PROMPT, return_tensors="pt").input_ids.to(DEVICE)embed = qwen.get_input_embeddings()@torch.no_grad()def describe(indices, max_new_tokens=20):"""Greedy continuation of the prompt, with the image vector spliced in. Also in batches: the model returns logits over the whole vocabulary at every position, and only the last one is read. """ written = []for start inrange(0, len(indices), WRITE_BATCH): part = indices[start:start + WRITE_BATCH] prefix = torch.cat([embed(prompt_ids).expand(len(part), -1, -1), adapter(features[part])], 1) tokens =Nonefor _ inrange(max_new_tokens): stream = prefix if tokens isNoneelse torch.cat([prefix, embed(tokens)], 1) nxt = qwen(inputs_embeds=stream).logits[:, -1].argmax(-1, keepdim=True) tokens = nxt if tokens isNoneelse torch.cat([tokens, nxt], 1) written += tokeniser.batch_decode(tokens, skip_special_tokens=True)return [t.strip() for t in written]@torch.no_grad()def agreement(indices, sentences):"""How well a caption matches its image, scored by CLIP itself.""" text = clip_processor(text=sentences, return_tensors="pt", padding=True, truncation=True, max_length=77).to(DEVICE) vectors = clip.text_projection(clip.text_model(**text).pooler_output) image = torch.nn.functional.normalize(features[indices], dim=-1)returnfloat((image * torch.nn.functional.normalize(vectors, dim=-1)).sum(-1).mean())before = describe(test_rows)print(f"CLIP agreement, untrained adapter: {agreement(test_rows, before):.4f}")print(f"CLIP agreement, the real captions: {agreement(test_rows, [captions[i] for i in test_rows]):.4f}")print("\nwhat it says now:")for sentence in before[:3]:print(f" {sentence!r}")
CLIP agreement, untrained adapter: 0.1882
CLIP agreement, the real captions: 0.3280

what it says now:
  ', a 1990s American comedy film directed by John Landis and starring John C'
  ''
  ''
That is the floor. Now train the adapter, and only the adapter, on image and caption pairs. The loss is on the caption words alone — the model is never asked to predict the image position.
Three seeds, because the thing being measured is a small movement on a score whose ceiling is close by, and one run cannot tell you how much of it was the initialisation.
Show the code
SEEDS = (0, 1, 2)def train(seed):"""One adapter from scratch. Everything either side of it stays frozen."""global adapter adapter = new_adapter(seed) optimiser = torch.optim.AdamW(adapter.parameters(), lr=LR) generator = torch.Generator().manual_seed(seed) floor = agreement(test_rows, describe(test_rows)) history = []for epoch inrange(EPOCHS): order = torch.randperm(len(train_rows), generator=generator).tolist() total = steps =0for start inrange(0, len(order) - BATCH +1, BATCH): batch = [train_rows[i] for i in order[start:start + BATCH]] text = tokeniser([" "+ captions[i] for i in batch], return_tensors="pt", padding=True, truncation=True, max_length=MAX_CAPTION).to(DEVICE) stream = torch.cat([embed(prompt_ids).expand(len(batch), -1, -1), adapter(features[batch]), embed(text.input_ids)], 1) labels = torch.cat([ torch.full((len(batch), prompt_ids.shape[1] +1), -100, device=DEVICE), text.input_ids.masked_fill(text.attention_mask ==0, -100)], 1) loss = qwen(inputs_embeds=stream, labels=labels).loss optimiser.zero_grad() loss.backward() optimiser.step() total += loss.item() steps +=1 history.append(total / steps) written = describe(test_rows)return floor, agreement(test_rows, written), history, writtenreference = agreement(test_rows, [captions[i] for i in test_rows])runs = [train(seed) for seed in SEEDS]print(f"{'seed':<6}{'loss':>8}{'before':>9}{'after':>9}{'gain':>9}{'of the gap':>13}")for seed, (floor, scored, history, _) inzip(SEEDS, runs):print(f"{seed:<6}{history[-1]:>8.4f}{floor:>9.4f}{scored:>9.4f}"f"{scored - floor:>9.4f}{(scored - floor) / (reference - floor):>12.1%}")gains = [scored - floor for floor, scored, _, _ in runs]print(f"\nthe captions a person wrote score {reference:.4f}")print(f"gain over {len(SEEDS)} seeds: {np.mean(gains):.4f}, "f"spread {min(gains):.4f} to {max(gains):.4f}")print(f"\nheld-out images, seed {SEEDS[-1]}:")for i, sentence inzip(test_rows[:4], runs[-1][3][:4]):print(f" said: {sentence!r}")print(f" ref: {captions[i]!r}")
seed      loss   before    after     gain   of the gap
0       2.6011   0.1882   0.2276   0.0394       28.2%
1       2.6425   0.1920   0.2092   0.0171       12.6%
2       2.6842   0.1888   0.2007   0.0119        8.6%

the captions a person wrote score 0.3280
gain over 3 seeds: 0.0228, spread 0.0119 to 0.0394

held-out images, seed 2:
  said:  'A man in a blue shirt is standing in front of a building with a sign that says "B'
  ref:   'The man in the button up shirt is sitting at a table.'
  said:  'Two men are playing a game of tennis. One of the men is serving the ball. The other'
  ref:   'A boy and three girls in blue school uniforms walk down a dirt-covered road.'
  said:  'A young boy is playing with a toy car in the grass. He is wearing a blue shirt and'
  ref:   'One child with a flower painted on her head, is wearing a red glittery outfit with a shawl and gloves, while her companion with a hat looks on.'
  said:  'A man in a blue shirt is holding a red and white flag and walking down a street. A'
  ref:   'Two women in summer wear ride beach cruiser tricycles on the concrete near the beach.'
Conclusion
Three things came out of building it.
The ceiling is the frozen encoder. Every caption is written from 512 numbers. The adapter climbs from 0.1897 to 0.2125 on CLIP’s own agreement score, averaged over three seeds, against 0.3280 for the captions a person wrote. That is a sixth of the gap, and then it stops. It never sees the image, only what CLIP kept, and anything the encoder discarded is gone before the language model is involved. Picking the encoder matters more than designing the adapter.
The metric and the ceiling are the same object here: scoring with CLIP measures how well the adapter recovers what the encoder encoded, not whether the caption is true.
One run would have told you anything you wanted. The three seeds close 28.2%, 12.6% and 8.6% of the gap. That spread is wider than most of the differences this post could have been written about.
Fluency comes free, grounding does not. After training, every caption is ordinary English in the right shape, and nothing in the adapter’s 1.5M parameters learned to write it — Qwen already could. Untrained, the same arrangement emits Chinese text and markdown fragments, because a noise vector is as good a prefix as any. The whole run is spent on which words, which is the only thing the pair could not already do.
Grounding needs pairs. Given too few, the adapter finds the average caption and stops attending to the image: one sentence about a man in a white shirt for every photograph, and CLIP agreement below where it started. The mapping from an image vector to a sentence is what has to be learned, and there is no shortcut to seeing enough of them.