A title, a timestamp, a link and an author against 872,556 real posts: what each input is worth, and why most of the outcome is in none of them.
Author
Rosh Beed
Published
June 11, 2026
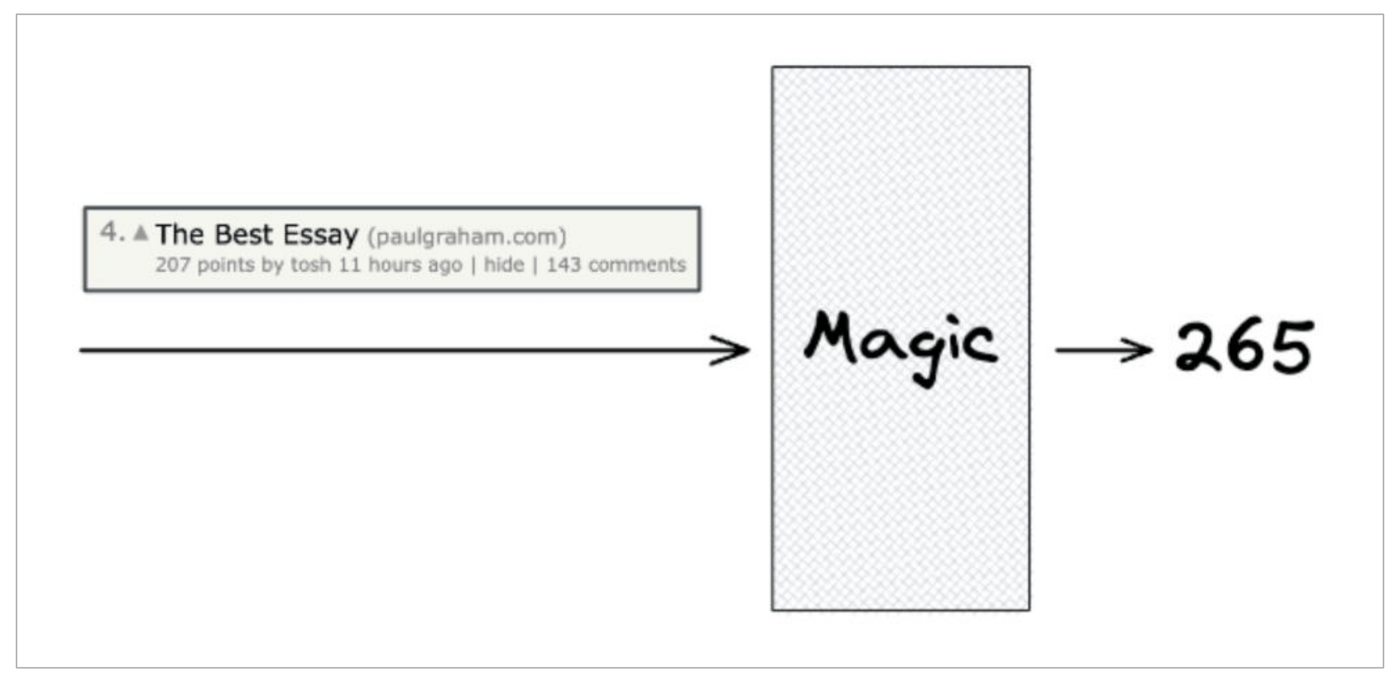
Predict how many upvotes a Hacker News post will get, from its title, where it links, when it was submitted and who by.
Three of those four are already numbers, or become one by looking up a category. The title is a free-text box, encoded the way word2vec encodes one: a learned vector per word, averaged into a single vector for the title.
872,556 real posts from November 2023 to August 2026, split by time rather than at random. Scores drift and posts from the same day compete for the same front page, so a random split would let the model see the future of its own test set.
The Data
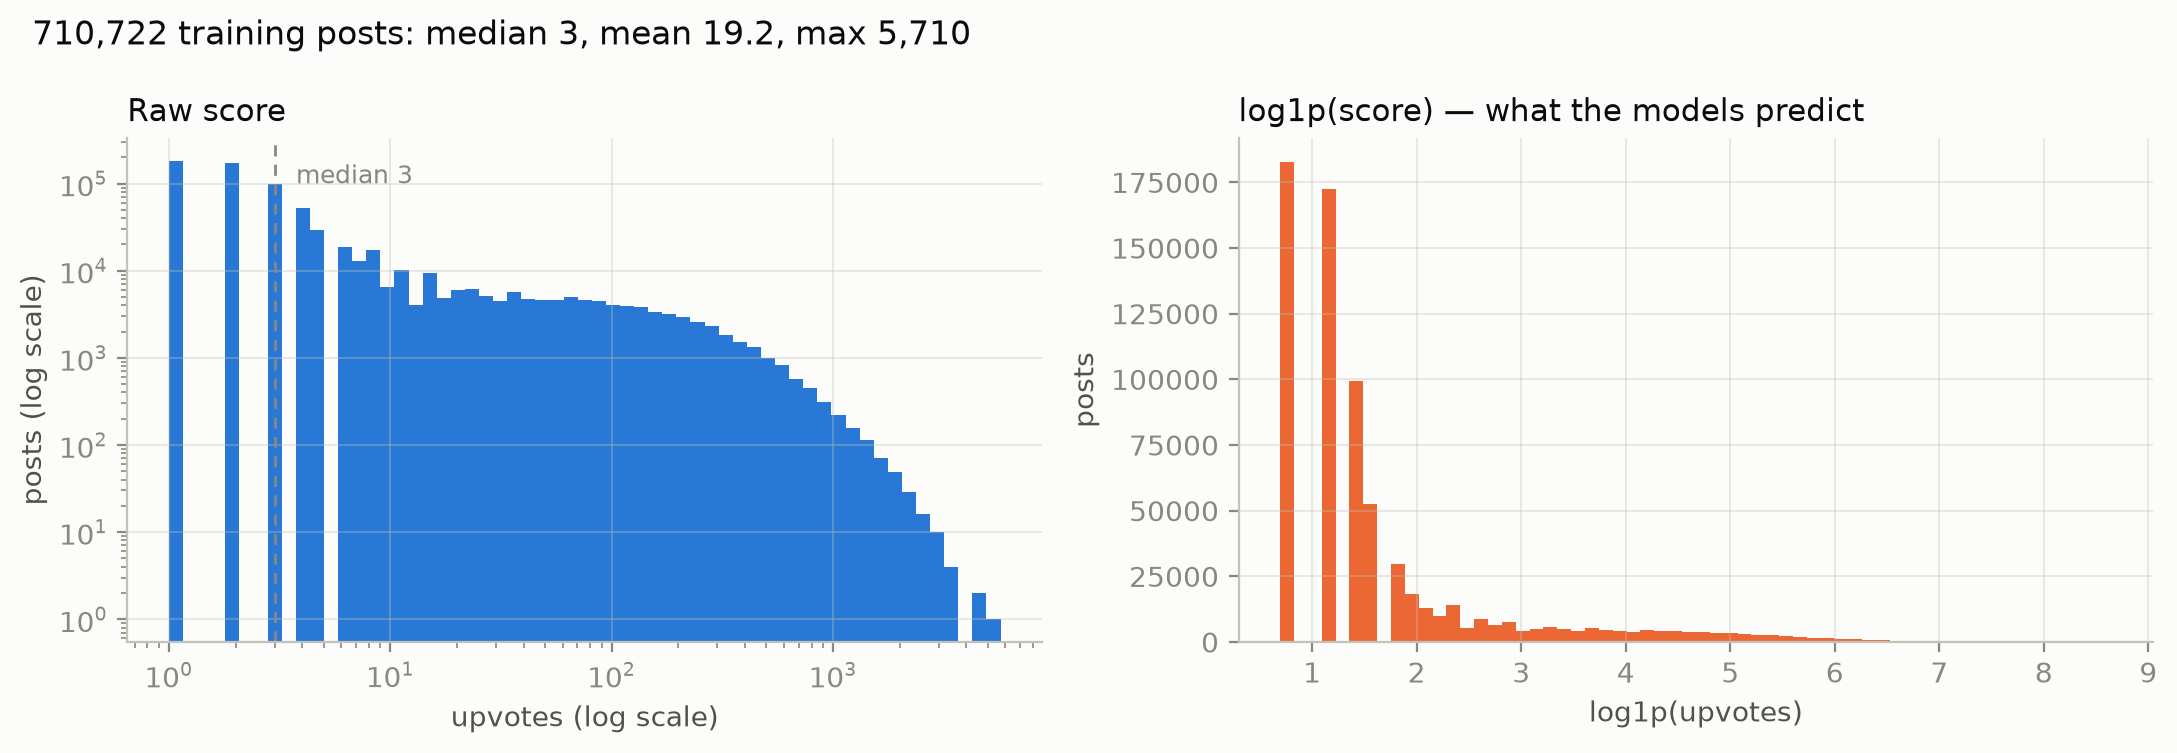
The median post scores 3. The maximum is 5,710. On a distribution this skewed the typical post and the average post are six times apart. That gap decides more than the architecture does.
One input is deliberately missing. The comment count predicts the score very well. It is also not known when a post is submitted. A model using it would score beautifully and answer a question nobody asked.
The author’s history has the same hazard, so it is built only from their earlier posts.
The Model
A post arrives as four different kinds of thing: some text, a timestamp, a link, an author. The model concatenates them and runs one stack over the lot: a first layer taking 329 inputs onto 256 hidden units, a 256 → 256 layer, then the head.
Combining them at the input is early fusion, as against giving each group its own network and adding the scores. The difference is what a summed model cannot represent: anything depending on two groups at once, a good title multiplying a good posting time rather than adding to it. It is worth almost nothing here except at the smallest widths, which a post of its own works through.
Show the code
# Setup, inlined rather than imported so this notebook runs on its own.# Keep it folded; nothing below it depends on anything outside this file.import matplotlib.pyplot as plt# --- chart styling -------------------------------------------------------# Categorical slots of a CVD-validated palette: blue, orange, aqua, purple.COLOURS = ["#2a78d6", "#eb6834", "#1baf7a", "#8a63d2"]MUTED, GRID, AXIS ="#5b6570", "#e6e6e3", "#d5d5d1"def style_axes(ax, xlabel=None, ylabel=None, grid="y"):"""Strip an axes back to the ink that carries information."""if xlabel: ax.set_xlabel(xlabel, color=MUTED, fontsize=9)if ylabel: ax.set_ylabel(ylabel, color=MUTED, fontsize=9)if grid: ax.grid(axis=grid, color=GRID, linewidth=0.8) ax.set_axisbelow(True)for side in ("top", "right"): ax.spines[side].set_visible(False)for side in ("left", "bottom"): ax.spines[side].set_color(AXIS) ax.tick_params(colors=MUTED, labelsize=9, length=0)return axdef figure(width=7.0, height=4.2, **kw): fig, ax = plt.subplots(figsize=(width, height), **kw)return fig, ax
Two single-input models are fitted beside it on the same stack, so the value of having both inputs can be read off rather than assumed.
model
first layer
then
parameters
metadata only
29 → 256
256 → 256 → 1
73,793
title only
300 → 256
256 → 256 → 1
143,169
title and metadata
329 → 256
256 → 256 → 1
150,593
Show the code
import reimport numpy as npimport pandas as pdimport torchimport torch.nn as nnfrom huggingface_hub import hf_hub_downloadfrom scipy.stats import spearmanrDEVICE = torch.device("mps"if torch.backends.mps.is_available() else"cpu")HN ="6700bf3f906f47c95bb79f077f553ccbaf86d38e"WORDS ="fdd78e1589d0816ea149cb680d6f29094ebd8c5d"posts = pd.read_parquet(hf_hub_download("roshbeed/ai-residency-hn-posts","hn_stories.parquet", repo_type="dataset", revision=HN))checkpoint = torch.load(hf_hub_download("roshbeed/ai-residency-word-embeddings","skipgram_model.pt", revision=WORDS), map_location="cpu", weights_only=False)vectors = checkpoint["model_state_dict"]["in_embed.weight"].numpy()word_id = checkpoint["extra"]["word_to_index"]posts = posts.sort_values("time").reset_index(drop=True)lower = posts["title"].fillna("").str.lower()tokenise =lambda s: re.findall(r"[a-z0-9\+#]+", s)MAX_TOKENS =32title_vectors = np.zeros((len(posts), vectors.shape[1]), dtype=np.float32)for row, title inenumerate(lower): ids = [word_id[w] for w in tokenise(title)[:MAX_TOKENS] if w in word_id]if ids: title_vectors[row] = vectors[ids].mean(0)print(f"{len(posts):,} posts, titles through {vectors.shape[0]:,} word vectors "f"of {vectors.shape[1]}")
872,556 posts, titles through 71,290 word vectors of 300
Every number the model reports below is computed from those posts. The features are the service’s: the title as a mean of its word vectors, and four groups of metadata around it.
Show the code
PREFIXES = ("show hn", "ask hn", "tell hn", "launch hn")DOMAIN_DIM =8when = pd.to_datetime(posts["time"], unit="s", errors="coerce")hour, weekday = when.dt.hour.fillna(0), when.dt.weekday.fillna(0)elapsed = (when - when.min()).dt.total_seconds().fillna(0) /86400.0temporal = np.stack([ np.sin(2* np.pi * hour /24), np.cos(2* np.pi * hour /24), np.sin(2* np.pi * weekday /7), np.cos(2* np.pi * weekday /7), (weekday >=5).astype(float), elapsed,], 1).astype(np.float32)url = posts["url"].fillna("")has_url = (url !="").astype(np.float32).to_numpy()[:, None]host = url.str.extract(r"https?://(?:www\.)?([^/]+)", expand=False).fillna("")common = host.value_counts().head(999).indexdomain_id = host.map({h: i +1for i, h inenumerate(common)}).fillna(0).astype(np.int64)tokens = lower.map(tokenise)surface = np.stack([ tokens.map(len), lower.str.len(), tokens.map(lambda t: np.mean([len(w) for w in t]) if t else0.0), lower.str.contains(r"\d").astype(float), lower.str.endswith("?").astype(float), posts["title"].fillna("").map(lambda s: sum(w.isupper() andlen(w) >1for w in s.split())), lower.str.contains(r"\[(?:pdf|video|audio|slides)\]").astype(float),*[lower.str.startswith(p).astype(float) for p in PREFIXES],], 1).astype(np.float32)# The author's own history, built only from posts before this one, so a row never# sees its own score. The running mean is over log upvotes rather than upvotes: one# viral post otherwise sets an author's history for good.author = posts["author"].fillna("")log_score = pd.Series(np.log1p(posts["score"].to_numpy(dtype=np.float64)), index=posts.index)by_author = log_score.groupby(author, sort=False)prior = by_author.transform(lambda s: s.expanding().mean().shift(1)).fillna(0).to_numpy()seen = author.groupby(author, sort=False).cumcount().to_numpy()author_feats = np.stack([prior, np.log1p(seen), (seen ==0).astype(float)], 1).astype(np.float32)GROUPS = {"the title": title_vectors.shape[1], "when you post": temporal.shape[1],"where it links": 1+ DOMAIN_DIM, "the title's shape": surface.shape[1],"the author": author_feats.shape[1]}dense = np.concatenate([title_vectors, temporal, has_url, surface, author_feats], 1)upvotes = posts["score"].to_numpy(dtype=np.float32)target = np.log1p(upvotes)# Split by time, not at random: the model is asked about posts written after every# post it trained on, which is the only split a deployed scorer ever gets.held_out = when >="2026-06-01"train_rows, test_rows = np.where(~held_out)[0], np.where(held_out)[0]# days_elapsed is scaled by the training period, so a held-out post sits past 1.0# rather than the scale being set by data the model has not seen.seconds = posts["time"].to_numpy(dtype=np.float64)start = seconds[train_rows].min()span =max(1.0, (seconds[train_rows].max() - start) /86400)temporal[:, 5] = ((seconds - start) /86400/ span).astype(np.float32)dense[:, GROUPS["the title"] +5] = temporal[:, 5]mean, deviation = dense[train_rows].mean(0), dense[train_rows].std(0) +1e-6dense = (dense - mean) / deviationX = torch.from_numpy(dense).to(DEVICE)DOM = torch.from_numpy(domain_id.to_numpy()).to(DEVICE)Y = torch.from_numpy(target).to(DEVICE)print(f"{sum(GROUPS.values())} inputs in {len(GROUPS)} groups: "+", ".join(f"{k}{v}"for k, v in GROUPS.items()))print(f"train on {len(train_rows):,} posts to May 2026; "f"held out {len(test_rows):,} from June, carrying {upvotes[test_rows].sum():,.0f} upvotes")
329 inputs in 5 groups: the title 300, when you post 6, where it links 9, the title's shape 11, the author 3
train on 803,281 posts to May 2026; held out 69,275 from June, carrying 1,309,690 upvotes
Each model is the same stack; the only difference is which of those groups reaches it.
Show the code
HIDDEN, BATCH, LR, WEIGHT_DECAY, EPOCHS, PATIENCE =256, 1024, 3.737e-4, 1.835e-4, 20, 5WIDTHS =list(GROUPS.values())class Scorer(nn.Module):"""One stack. `keep` is which input groups reach it."""def__init__(self, keep=None):super().__init__()self.keep = keep # None means every groupself.domain = nn.Embedding(1000, DOMAIN_DIM)self.first = nn.Linear(sum(WIDTHS), HIDDEN)self.rest = nn.Sequential(nn.ReLU(), nn.Linear(HIDDEN, HIDDEN), nn.ReLU(), nn.Linear(HIDDEN, 1))def assemble(self, x, dom): split = WIDTHS[0] + WIDTHS[1] +1# the learned domain sits after has_url full = torch.cat([x[:, :split], self.domain(dom), x[:, split:]], 1)ifself.keep isnotNone: full = full *self.keepreturn fulldef forward(self, x, dom):returnself.rest(self.first(self.assemble(x, dom))).squeeze(-1)def fit(keep=None, seed=0): torch.manual_seed(seed) model = Scorer(keep).to(DEVICE) optimiser = torch.optim.AdamW(model.parameters(), lr=LR, weight_decay=WEIGHT_DECAY) generator = torch.Generator().manual_seed(seed) rows = torch.from_numpy(train_rows).to(DEVICE) test = torch.from_numpy(test_rows).to(DEVICE) best, waited, kept =1e9, 0, Nonefor _ inrange(EPOCHS): order = rows[torch.randperm(len(rows), generator=generator).to(DEVICE)]for i inrange(0, len(order) - BATCH, BATCH): b = order[i:i + BATCH] loss = nn.functional.mse_loss(model(X[b], DOM[b]), Y[b]) optimiser.zero_grad() loss.backward() optimiser.step()with torch.no_grad(): predicted = model(X[test], DOM[test]).cpu().numpy() error =float(np.mean((predicted - target[test_rows]) **2))if error < best: best, kept, waited = error, predicted, 0else: waited +=1if waited >= PATIENCE:breakreturn kept, modeldef group_mask(names): keep = torch.zeros(sum(WIDTHS), device=DEVICE) at =0for name, width in GROUPS.items():if name in names: keep[at:at + width] =1.0 at += widthreturn keepSEEDS = (0, 1, 2)actual = upvotes[test_rows]trained = {"title only": [fit(keep=group_mask({"the title"}), seed=s) for s in SEEDS],"metadata only": [fit(keep=group_mask(set(GROUPS) - {"the title"}), seed=s) for s in SEEDS],"title and metadata": [fit(seed=s) for s in SEEDS],}runs = {name: [p for p, _ in pairs] for name, pairs in trained.items()}models = [m for _, m in trained["title and metadata"]]
Show the code
def summarise(predictions):"""Back to upvotes from log-upvotes, then the columns the table reports.""" counts = np.expm1(np.mean(predictions, axis=0)) rho = np.mean([spearmanr(p, target[test_rows])[0] for p in predictions])return (np.median(np.abs(counts - actual)), counts.mean(), counts.max(), counts.sum() / actual.sum(), rho)average = np.full(len(actual), np.expm1(target[train_rows].mean()))print(f"{'model':<26}{'median err':>11}{'mean pred':>11}{'highest':>9}"f"{'share':>8}{'spearman':>10}")print(f"{'what actually happened':<26}{'--':>11}{actual.mean():>11.1f}"f"{actual.max():>9.0f}{'100%':>8}{'--':>10}")print(f"{'guess the average':<26}{np.median(np.abs(average - actual)):>11.1f}"f"{average.mean():>11.1f}{average.max():>9.0f}"f"{average.sum() / actual.sum():>7.0%}{0.0:>10.4f}")for name, predictions in runs.items(): median, mean_pred, highest, share, rho = summarise(predictions)print(f"{name:<26}{median:>11.1f}{mean_pred:>11.1f}{highest:>9.0f}"f"{share:>7.0%}{rho:>10.4f}")
model                      median err  mean pred  highest   share  spearman
what actually happened             --       18.9     3158    100%        --
guess the average                 2.2        4.2        4    22%    0.0000
title only                        1.9        4.4       75    23%    0.2631
metadata only                     1.8        4.4      140    23%    0.3421
title and metadata                1.8        4.6      203    25%    0.3530
Results
Held-out June to August 2026, each row the mean of three seeds.
Look at the share column before anything else. Every model predicts about a quarter of the upvotes that actually happened, because the objective is mean squared error on log1p(score) and the exponential of an average log is not the average. The model ranks; it does not count. That is a property of the objective, not a bug in the training, and it is why the service is scored on rank correlation.
On rank it does real work: 0.35 against 0 for guessing the average.
The column I care about after that is the highest prediction. The served model will say a few hundred for the right post, an order of magnitude above its own mean. It can call a front-page hit, and those are the posts anyone cares about.
Neither input alone is the best model. The title alone ranks at 0.263 and the metadata alone at 0.342, against 0.353 for the two together.
Show the code
base = np.mean([spearmanr(p, target[test_rows])[0] for p in runs["title and metadata"]])test = torch.from_numpy(test_rows).to(DEVICE)print(f"the combined model scores {base:.4f}; zeroing one group at inference:\n")print(f"{'input removed':<22}{'effect':>9}")for name in GROUPS: keep = group_mask(set(GROUPS) - {name}) scores = []for model in models:# The model keeps the weights it trained with; the group is blanked on the way# in. Retraining without it would let the others quietly take over its job. model.keep = keepwith torch.no_grad(): scores.append(spearmanr(model(X[test], DOM[test]).cpu().numpy(), target[test_rows])[0]) model.keep =Noneprint(f"{name:<22}{np.mean(scores) - base:>+9.3f}")
the combined model scores 0.3530; zeroing one group at inference:

input removed            effect
the title                -0.060
when you post            -0.054
where it links           -0.042
the title's shape        -0.030
the author               -0.054
Which Inputs Matter
Zero one input at a time and see what the prediction loses. The model keeps the weights it trained with — blanking a group at inference asks what it leans on, where retraining without the group would only show how well the others cover for it.
The title costs the most to lose, at 0.060 of rank correlation. When you post and who posted it are worth the same as each other to three decimals, and where it links a little under that. Nothing here is dead weight: every one of the five costs something when it goes.
The Ceiling
All of which sits under a harder limit. The counts in this section come from the service’s own pass over the same corpus rather than from the run above.
A quarter of all linked posts are reposts: 85,340 URLs submitted more than once. That gives a natural experiment, because the content is held fixed and everything else varies. The two scores agree only weakly. Among URLs whose first submission scored between 2 and 5, the second submission reached a maximum of 2,645.
Knowing that identical content has already hit the front page roughly doubles the odds it will again, from 5.6% to 11.3%. That is all it buys. The content explains some of the outcome and timing, luck and whoever happened to be reading explain a lot of the rest.
There is a second ceiling, closer to home. This model averages word vectors, and averaging throws away word order, so Google acquires OpenAI and OpenAI acquires Google are the same input. A fine-tuned sentence transformer reads the difference and scores better. A deeper network on the same averaged vectors does not. The limit is the representation, not the model.
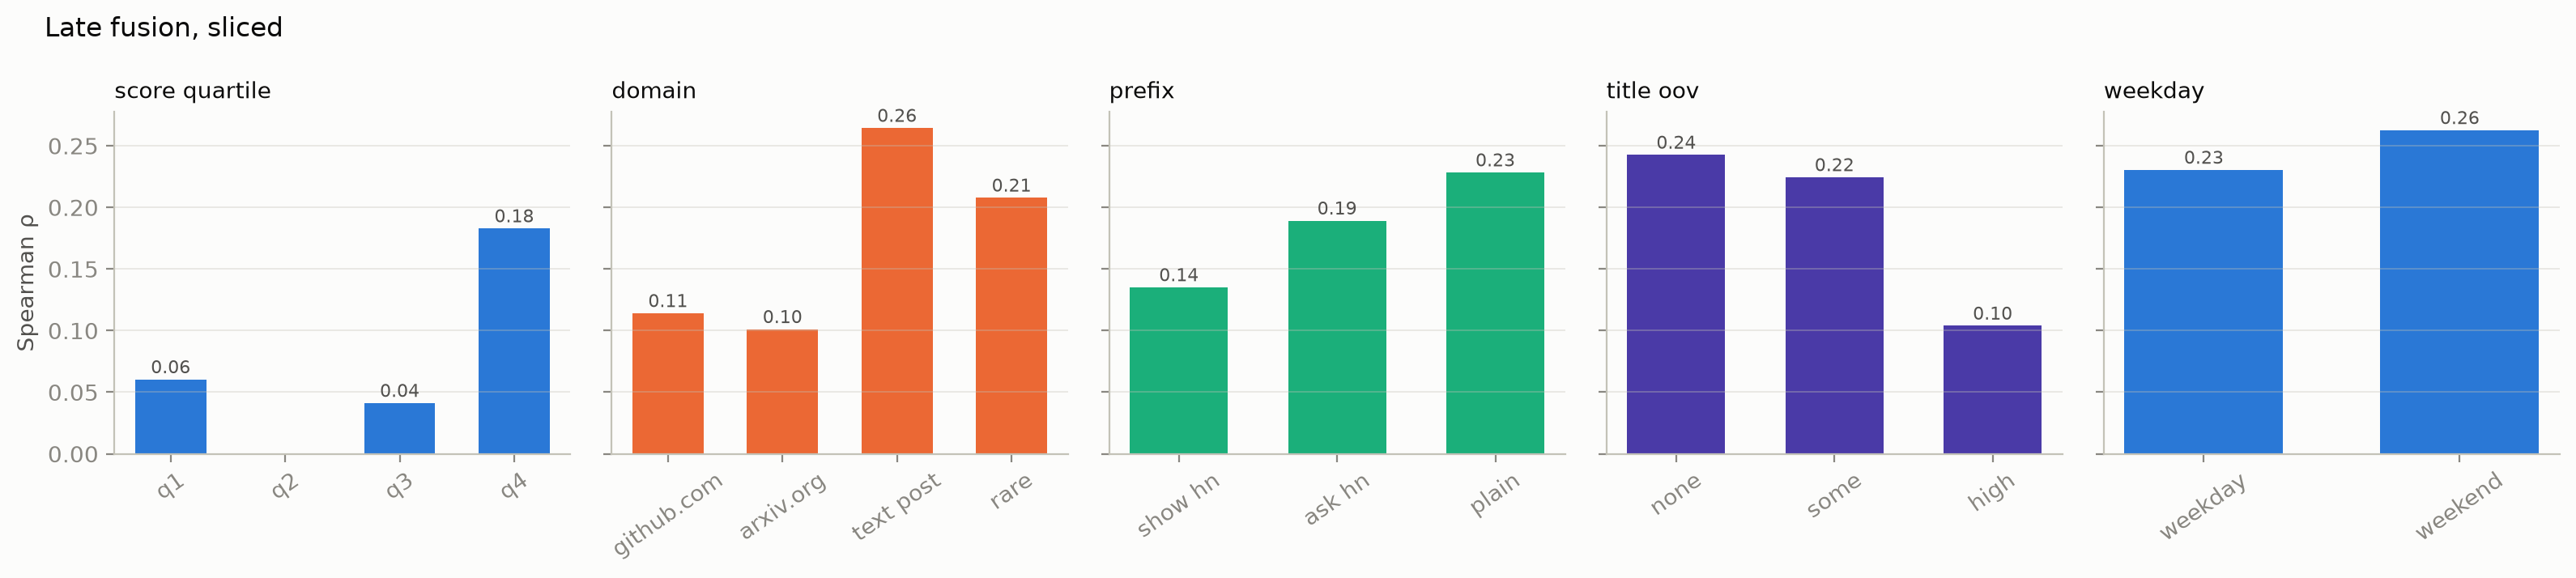
Show HN posts are the hardest slice, which makes sense: they compete on what was built rather than on how it was described, and a title carries less of that.
Conclusion
The title carries the most signal, and the author’s history is second
Combining inputs beats either alone
The representation is the ceiling, not the depth of the model
Most of the outcome is luck, and no model fixes that